How to Track ChatGPT Brand Mentions and Measure What Matters
Measure generative engine optimization (GEO) through ChatGPT mentions, citations and referrals, with original research on prompt tracking and monitoring costs.
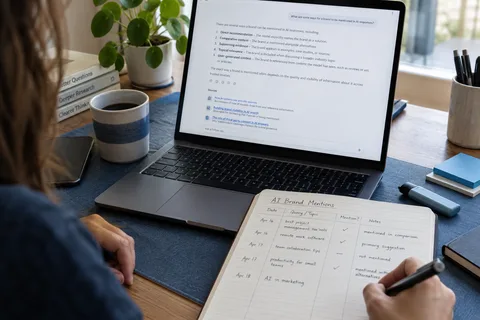
To track ChatGPT brand mentions, save answers to a consistent set of customer questions and record whether your business is named, whether your website is cited and what the answer says. Then measure referral visits and qualified inquiries separately.
Brand tracking is a measurement task within generative engine optimization (GEO). A mention-tracking tool observes a sample of answers. Its score is not a count of everyone who saw your brand in private ChatGPT conversations.
For this update, we reviewed five AI visibility providers' public plans and documentation on September 20, 2026. The clearest practical finding was that prompt allowances, check budgets and one-time trials describe different amounts of monitoring. We did not run a brand-visibility experiment or test the vendors' detection accuracy.
GEO measurement: mentions, citations and referrals
| Event | What to record | What it does not prove |
|---|---|---|
| Brand mention | Your business is named in the saved answer | A link, recommendation or customer visit |
| Website citation | A source link points to your domain | That someone clicked it |
| Referral visit | Analytics attributes a visit to the assistant | That every AI exposure is captured |
| Qualified inquiry | A relevant prospect contacts the business | That AI alone caused the inquiry |
Also record incorrect statements. A mention that gets your service area or opening hours wrong can be more urgent than a small change in a visibility score.
Our research: how much monitoring fits in a plan?
Ahrefs' custom-prompt documentation defines an ordinary check around one prompt, one model and one location. Using that unit, we calculated the following illustrative workload:
| Panel and schedule | Checks in a 30-day month |
|---|---|
| 12 prompts × 3 engines × 1 location, daily | 1,080 |
| 12 prompts × 3 engines × 2 locations, daily | 2,160 |
Its documented 2,500-check budget therefore fits 27 complete daily prompts across three engines in one location, or 13 in two locations. These are budget calculations, not measured mentions. They assume ordinary check weights and one run per combination per day; different engine weights or repeated runs can use more.
By comparison, Peec Starter listed 50 prompts across three selected models with daily collection. Its allowance implies 4,500 answers in a modeled 30-day month. More collected answers do not establish that one product is more accurate or useful.
Our provider dataset, calculation results and methodology make those inputs inspectable. The full tool comparison covers the five providers' prices and billing differences.
Build a question panel around real decisions
Start with questions customers ask before buying. For a local service business, cover the service, location, relevant constraints and comparisons customers actually make.
Include unbranded questions such as “Who repairs tankless water heaters in this town?” separately from branded questions such as “Does this company service tankless systems?” The first tests discovery within your sample; the second tests what the answer says when you supply the business name.
Keep the wording stable while comparing periods. Record the selected location and any location written into the prompt. A model's interface, search setting, account context and conversation history can affect the answer, so log the conditions you can observe. Do not assume an API response reproduces the consumer interface.
If you add questions later, identify them as a new group. Otherwise, a changing denominator can make a score look better or worse even when the original questions behave the same way.
Keep the answer behind every number
For each run, save the date, engine or product surface, prompt text, location, returned answer, mentioned brands and cited URLs. Mark failed runs separately. A timeout is not an answer that omitted your brand.
A simple sampled mention rate is:
Completed answers naming your brand ÷ completed answers in the defined panel.
Report the numerator and denominator alongside the percentage. Separate branded from unbranded questions and keep engines identifiable. If results move, inspect the underlying answers before attributing the change to a recent website edit.
A one-time trial can help you inspect a report, but it cannot supply a trend by itself. On the review date, Profound's live brands pricing page described its trial as ten prompts run once on ChatGPT, with ongoing Enterprise terms quoted separately.
Connect answer sampling to referral measurement
OpenAI's publisher FAQ says ChatGPT adds utm_source=chatgpt.com to referral URLs. Check both campaign attribution and referral reporting in your analytics setup, then test what your own installation records.
Some people will not click. Others may later search for the business or contact it directly. Analytics therefore gives you an observable referral path, not a complete census of AI-influenced customers.
For Google, Search Console now has a Generative AI performance report. Read its metric definitions and coverage rather than assuming it measures ChatGPT or matches a third-party prompt panel. Keep each source labeled in your reporting.
Use the findings to choose a specific next action
An incorrect factual answer may point to conflicting business information. A relevant citation to an outdated page may justify updating that page. Repeated competitor mentions can prompt a closer look at the sources and the question's intent, without proving that copying a competitor will change the next answer.
Keep an edit log and compare the same panel after the change. Describe any movement as an observation unless you have evidence that supports a causal claim.
If the problem is the quality or clarity of your own information, our generative engine optimization (GEO) guide explains what to check. Contact Lookelo when you need help turning those findings into website changes.
Choose prompts that answer different business questions
Use a mix of branded and unbranded questions. A branded question helps you inspect what an assistant says when someone already knows the business. An unbranded question helps you observe whether it appears in a broader search for products or services. Neither is a sample of every customer conversation.
| Prompt type | Retail question to adapt | What to inspect |
|---|---|---|
| Branded | What services does [store name] offer? | Whether the store information is accurate |
| Category and location | Where can I buy exterior paint in [town]? | Which businesses and sources appear |
| Comparison | How do [store A] and [store B] compare for paint advice? | The claims made about each business |
| Problem-solving | What should I check before painting a damp basement wall? | Which advice and supporting sources are returned |
Start with questions customers actually ask your team. Record the exact wording and collection conditions, then keep the panel stable enough to compare. Add new questions deliberately and label the change so a different sample is not mistaken for an improvement in performance.